This Week in Crypto Law (November 15, 2026)
Law and Ledger is a news segment focusing on crypto legal news, brought to you by Kelman Law – A law firm…
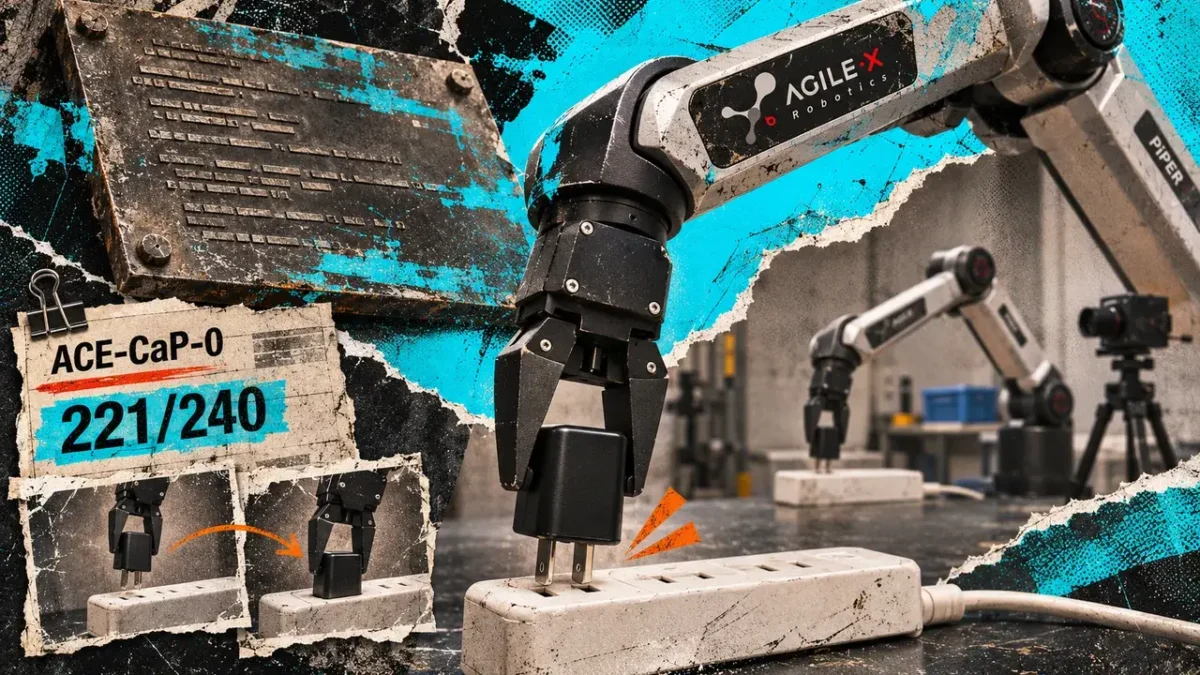
ACE-CaP-0's frozen task programs ran without a coding agent in the loop after development with human assistance available. Read the full story on CryptoSlateUnderstand the crypto stories that matter and…
Make CryptoSlate preferred on
Share Share
Robot programs developed by Anthropic’s Claude Opus 5.5 coding agent completed 221 of 240 physical evaluation trials, ACE-CaP-0 researchers reported in a study posted November 12. The result shows that task-specific skills can persist in code and run without the coding agent choosing each action.
The researchers behind ACE-CaP-0, a method for developing robot control programs, reported a 92.1% success rate across eight tasks. Each program was frozen before 30 separate evaluation trials, with no further updates. Human guidance and demonstrations were available during development.
The experiment separates program development from repeated execution. The agent’s work produced a program that could be used repeatedly. During evaluation, that program still used perception and control systems to respond to observations, while its decision rules stayed fixed. Neither a human nor the coding agent remained in the execution loop.
ACE-CaP-0 separates assisted program development from repeated execution with live perception and control.
Human assistance is available during development; the frozen task program runs without a human or coding agent in the execution loop.
Authors’ preprint account. Development permits human assistance; demonstration-collection resets are excluded from the ten-reset budget. Repeated execution on tested tasks does not establish reuse under new conditions.
Sources and evidence
Source-bound qualitative process diagram from sections 2 to 4. Arrows show code revision and runtime sensing relationships, not timing, trial quantities or comparative efficiency.
Authors’ preprint account. Development permits human assistance; demonstration-collection resets are excluded from the ten-reset budget. Repeated execution on tested tasks does not establish reuse under new conditions.
Infographic by CryptoSlate
Author-reported successful trials out of 30 for each frozen program. These were physical evaluation trials, separate from development; Table 1, November 12 preprint.
Retry chartChart by CryptoSlate
Source: ACE-CaP-0, Table 1
View dataHide dataSuccess varied across the eight tasksCategorySuccessful trials (out of 30)Charger insertion (30/30)30Bread packing (25/30)25Bottle uncapping (27/30)27Cup nesting (28/30)28Flower insertion (27/30)27Chicken plating (29/30)29Parcel reorientation (28/30)28Shoe packing (27/30)27
The physical setup used two Agilex PIPERX arms and three cameras. Tasks included inserting a charger, uncapping a bottle and packing shoes. Charger insertion succeeded in all 30 trials; bread packing, the weakest result, succeeded in 25. Mean physical execution times across tasks ranged from 0.97 to 2.27 minutes.
During development, the coding agent wrote, ran, inspected and revised its code using physical feedback. It could ask for textual advice or demonstrations in which a person physically guided the robot arms. Those demonstrations supplied video, arm trajectories and key joint poses.
Development allowed at most ten human-assisted scene resets per task. Resets used to collect demonstrations were excluded, and the budget counted scene resets rather than all robot executions or demonstrations.
The agent could also use simulated experiments when they helped resolve a development question. In a charger-insertion comparison, on-demand simulation produced a program with 100% evaluation success, versus 86.7% for development without simulation. The comparison used one development run per condition.
That comparison also illustrates a cost trade-off. Development took 2.6 hours with on-demand simulation versus 3.7 hours without it, while output-token usage increased from 730,000 to 1,090,000. The time and token figures leave total development costs unresolved; the researchers call for accounting that includes demonstration effort.
Repeating evaluation trials measures how the resulting program performs. Establishing how consistently the development process produces an equally capable program requires separate development runs across tasks.
ACE-CaP-0 leaves behind task-specific programs that can execute repeatedly with fresh observations and fixed decision rules. The study provides evidence for that form of skill reuse after human-assisted development. Testing those routines under new conditions is the next step toward establishing how broadly they can be reused.
Liam ‘Akiba’ Wright Editor-in-Chief • CryptoSlate
Also known as “Akiba,” Liam Wright is a reporter, podcast producer, and Editor-in-Chief at CryptoSlate. He believes that decentralized technology has the potential to make…
AI
2 min read 1 day ago
Nov 14, 2026 Bearish
Law and Ledger is a news segment focusing on crypto legal news, brought to you by Kelman Law – A law firm…
Brazil's central bank stance on stablecoin conversions could reshape fintech operations, emphasizing stricter compliance and potential market shifts. The post Brazil’s central…
Law and Ledger is a news segment focusing on crypto legal news, brought to you by Kelman Law – A law firm…
Angry Token price today, ANGRYTOKEN to USD live price, marketcap and chart CoinDesk